Living draft. This chapter reflects the sources cited below and will be revised as further sources are incorporated. Found an error? Use the Report an issue link in the sidebar.
11.1 Definition
The question cepstral peak prominence asks is how strongly a harmonic pattern stands out from the background. Unlike jitter and shimmer it never needs to find where one cycle ends and the next begins, which is why it survives in voices where cycle-by-cycle measures do not.
Cepstral peak prominence (CPP) quantifies how strongly the harmonic structure of a voice signal emerges from its background. The cepstrum used in voice analysis is obtained by transforming the waveform into a spectrum, taking the logarithm, and transforming again; its horizontal axis is a time-like dimension called quefrency(Murton et al. 2020). The periodic harmonic peaks of the spectrum collapse into a single dominant cepstral peak at the quefrency of the voice period. The height of that peak above a regression line through the whole cepstrum is the CPP, reported in decibels (Murton et al. 2020). The amplitude of the dominant cepstral peak (the first rahmonic) reflects the strength with which the fundamental frequency emerges from competing background frequencies (Maryn et al. 2009).
Lower CPP values are associated with greater dysphonia severity (Murton et al. 2020). Two properties distinguish CPP from the classical perturbation measures. First, it can be extracted from connected speech as well as sustained vowels. Second, it does not require direct computation of the fundamental frequency, so no pitch detection or tracking is needed — which makes cepstral measures robust in dysphonic and particularly in breathy voices, where period-by-period analysis breaks down (Murton et al. 2020; Barsties v. Latoszek et al. 2018). The 2018 ASHA instrumental-assessment guidance recommended CPP as a general measure of dysphonia, replacing jitter, shimmer, and harmonics-to-noise ratio in that role (Murton et al. 2020).
11.2 Computation
The waveform is Fourier-transformed into a spectrum, the logarithm of the spectrum is taken, and a second (inverse) Fourier transform carries the result into the cepstral domain (Murton et al. 2020). A linear regression line relating quefrency to cepstral magnitude is fitted through the cepstrum, and CPP is the difference in amplitude between the cepstral peak and the point on the regression line directly below it (Maryn et al. 2009; Barsties v. Latoszek et al. 2018).
CPP versus CPPS. Averaging the cepstrum first across time and then across quefrency yields a smoothed cepstrum; the same peak-minus-regression-line measurement on the smoothed cepstrum is the smoothed cepstral peak prominence, CPPS (Maryn et al. 2009). Hillenbrand and colleagues developed SpeechTool, a program that derives the unsmoothed cepstrum; a later modification of the algorithm, averaging across time and then across quefrency, produced the smoothed cepstrum (Maryn et al. 2009).
Praat and SpeechTool CPPS are on different scales.Maryn and Weenink (2015) compared SpeechTool’s original CPPS with Praat’s implementation on a sustained vowel and continuous speech from 289 subjects with voice disorders. The two correlate almost perfectly, but their numerical ranges differ by about 5 dB: mean CPPS was 6.61 dB in SpeechTool against 11.66 dB in Praat, on the same recordings. The relation between them is y = 1.4387x + 2.1543 with r² = 0.924. A cutoff obtained in one program cannot be applied to a value computed in the other without that conversion. The strength of the correlation means the two measure the same thing; it does not make the numbers interchangeable. The corresponding comparison for the index built on CPPS is much closer in scale: the Praat-only AVQI accounted for 96.0% of the variance of the SpeechTool-based AVQI, with means of 3.97 against 3.83 (Maryn and Weenink 2015).
Software implementations. Three computation algorithms dominate the clinical literature: Hillenbrand and Houde’s CPPS algorithm, Praat’s CPPS algorithm, and the CPP computation in Analysis of Dysphonia in Speech and Voice (ADSV, PENTAX Medical) (Murton et al. 2020). Their parameter choices differ in ways that matter:
ADSV applies a voicing activity detector, and frames with negative CPP (cepstral peak below the regression line) are excluded from analysis (Murton et al. 2020).
Praat computes CPPS from a PowerCepstrogram and includes no voicing activity detection. The reference configuration used by Murton et al. (2020): 60-Hz pitch floor, 2-ms time step, 5-kHz maximum frequency, pre-emphasis from 50 Hz, time averaging window 0.01 s, quefrency averaging window 0.001 s, peak search range 60–330 Hz, parabolic interpolation, straight tilt line over the quefrency range 0.001–0 s, robust fit.
Because of these differences, values from different programs live on different scales and are not interchangeable (see Confounds and cautions).
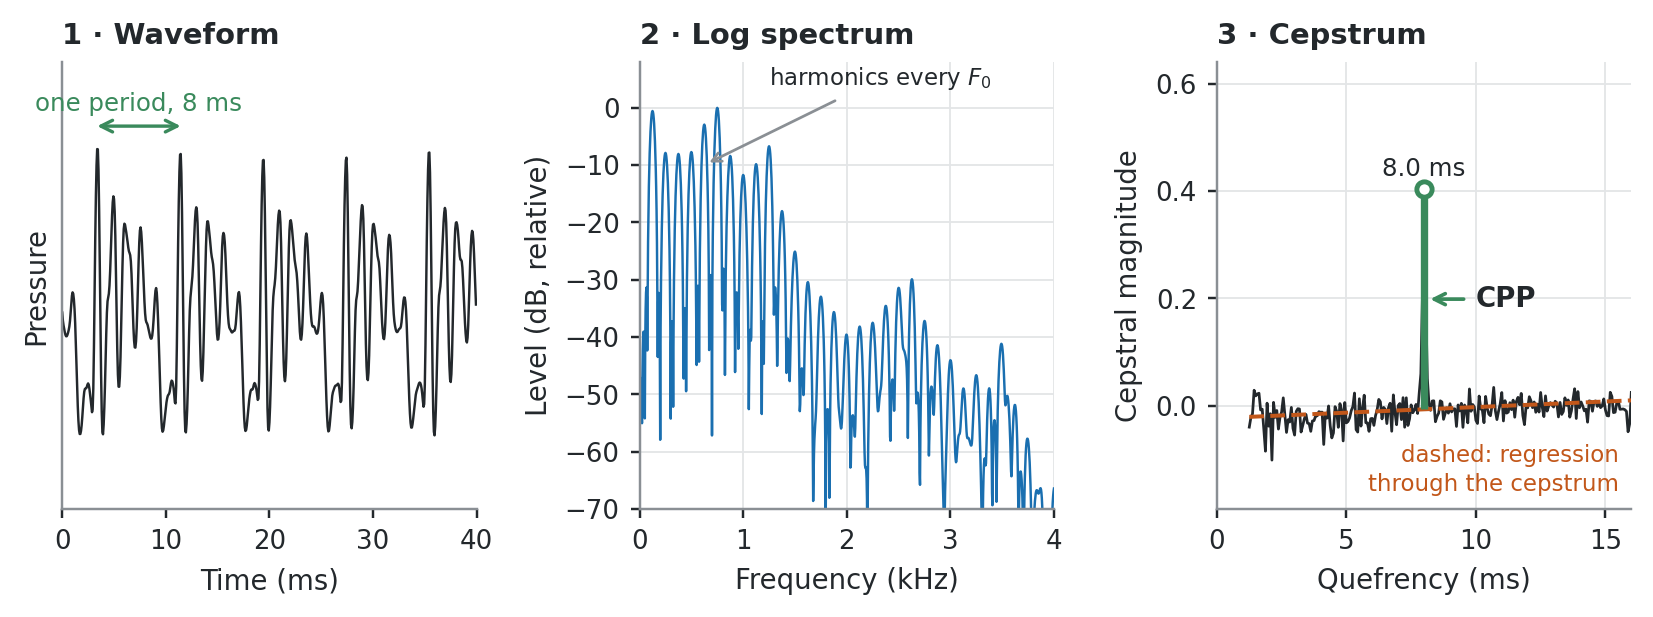
Figure 11.1 follows one frame through all three domains: the waveform, the comb of harmonics in its spectrum, the single cepstral peak the comb collapses into, and the distance that is reported as CPP.
Figure 11.1: What the measurement is, on one 40-ms frame of a synthetic vowel (F0 = 125 Hz). 1 the waveform, repeating every 8 ms. 2 its log spectrum, a comb of harmonics spaced by F0. 3 the cepstrum of that spectrum, in which the whole comb collapses into a single peak at a quefrency of 8.0 ms — the voice period, and the reciprocal of 125 Hz. CPP is the vertical distance from that peak to the regression line fitted through the cepstrum, marked in green. The near-zero quefrency region, which carries the spectral envelope rather than the harmonic spacing, is outside the plotted range. The vertical scale in panel 3 is cepstral magnitude in log units; programs report CPP in decibels. The three domains are treated generally in Signal Fundamentals. Signal is synthetic and illustrative.
11.3 What it captures
CPP behaves as a general index of overall dysphonia severity. In the Massachusetts Eye and Ear Infirmary (MEEI) data of Murton et al. (2020), CPP values below task- and software-specific cutoffs indicated the presence of a voice disorder with up to 94.5% accuracy, and ADSV CPP estimated mean listener ratings of overall severity with r² from .5 to .74 depending on task (Praat CPPS: r² from .38 to .72). Regression lines allow a severity estimate from CPP; a Praat CPPS of 10 dB on sustained /a/ predicts a CAPE-V overall severity of approximately 54 (Murton et al. 2020).
Meta-analytically, CPP and CPPS are the best acoustic predictors of breathiness, and the only acoustic markers that reached the validity criterion for breathiness in both sustained vowels and continuous speech (Barsties v. Latoszek et al. 2018). Pooled effect sizes:
For roughness, CPPS reached the acceptability criterion only in continuous speech, where it was the only adequate predictor; CPPS does not, however, seem to distinguish the subtypes roughness and breathiness from each other well (Barsties v. Latoszek et al. 2018). Although the cepstral measures were originally designed for breathiness, they proved to be the most accurate acoustic measures of overall dysphonia severity (Barsties v. Latoszek et al. 2018).
In severely aperiodic and alaryngeal voices, where perturbation measures fail for lack of a reliably detectable fundamental period, CPP remains computable: in tracheoesophageal speakers it was the strongest single acoustic correlate of overall voice quality (rs = .78, about 60% of variance explained), and a two-factor regression combining CPP with the height of the second spectral harmonic reached rs = .87 with listener rankings (Maryn et al. 2009). That multivariate strategy is the same one the AVQI applies to laryngeal voice.
11.4 Normative data
CPP values and cutoffs belong to the pipeline that produced them: the program, its version and settings, and the speech material. Each row below states its pipeline and its compatibility class; see Pipeline Dependence and Reference Values for the classes. Compare a measured value only with a row whose pipeline matches.
Table 11.2: Diagnostic cutoffs (voice disorder vs. typical voice). MEEI rows: Murton et al. (2020). Second-sentence rows: Sauder et al. (2017). Sustained /i/: Buckley et al. (2023). PVQD row: Lucero (2026), a candidate cutoff from an exploratory analysis.
Population
Task
Pipeline
Cutoff
Accuracy
Class
MEEI, English; 295 patients, 50 controls
Sustained /a/
ADSV 3.4.2 CPP, default settings
11.46 dB
79.4%
pipeline-compatible
MEEI, English; 291 patients, 50 controls
Rainbow Passage, first 12 s
ADSV 3.4.2 CPP, default settings
6.11 dB
87.7%
pipeline-compatible
MEEI, English; 295 patients, 50 controls
Sustained /a/
Praat 6.0.40 CPPS, Watts et al. settings
14.45 dB
77.4%
pipeline-compatible
MEEI, English; 291 patients, 50 controls
Rainbow Passage, first 12 s
Praat 6.0.40 CPPS, Watts et al. settings
9.33 dB
94.5%
pipeline-compatible
English; 100 voice-disordered, 70 controls
Rainbow Passage, second sentence
Praat 6.0.17 CPPS, factory settings
19.10 dB
AUC 0.91
pipeline-compatible
PVQD, American English; 181 patients, 109 controls
The PhonaLab PVQD row is not comparable to the Praat rows above it, and the reason is settings rather than software. Those rows use the Watts et al. settings; this one uses the configuration of the official AVQI/ABI script: PowerCepstrogram with pitch floor 60 Hz, time step 0.002 s, maximum frequency 5000 Hz and pre-emphasis from 50 Hz, then CPPS with a time averaging window of 0.01 s, a quefrency averaging window of 0.001 s, peak search over 60 to 330 Hz, parabolic interpolation, a straight trend line with robust fit, and no tilt subtraction before smoothing (Lucero 2026). Same measure name, same engine family, different settings, so this row’s cutoff and the Watts-settings cutoff for the same task are not two estimates of one quantity.
Its cutoff is a candidate. The analysis was exploratory, with sensitivity 58.4% and specificity 87.8% on resubstitution, and 57.9% and 83.6% under ten-fold cross-validation (Lucero 2026). PhonaLab displays 13.33 dB as a boundary, so the exploratory label belongs wherever the number is shown.
Other reported cutoffs are listed below for context only. Their pipelines are incomplete where they are reported: no software version, or values read from another paper’s summary table. They are not used as cutoffs here.
Table 11.3: Reported cutoffs without a complete pipeline, shown as history. Normal vs. dysphonic except Heman-Ackah 2003 (mild vs. severe). Sauder row: Sauder et al. (2017); other rows as tabulated by Murton et al. (2020).
Study
Language
Pipeline
Sustained vowel
Running speech
Class
Sauder et al. 2017
English
ADSV CPPS, factory settings; ADSV version not stated
—
5.53 dB (second sentence of the Rainbow Passage; AUC 0.81)
unclassified (no software version)
Heman-Ackah et al. 2003
English
CPPS (Hillenbrand)
10 dB
5 dB
unclassified (as tabulated by Murton et al.)
Heman-Ackah et al. 2014
English
CPPS (Hillenbrand)
—
4.0 dB
unclassified (as tabulated by Murton et al.)
Yu et al. 2018
Korean
ADSV CPP
12 dB
7 dB
unclassified (as tabulated by Murton et al.)
Delgado-Hernández et al. 2019
Spanish
Praat CPPS (AVQI configuration)
13.96 dB
8.37 dB
unclassified (as tabulated by Murton et al.)
The two Hillenbrand rows show why the class matters. Their running-speech values, 5 dB and 4.0 dB, are not low versions of the Praat values elsewhere in this chapter; they sit on the SpeechTool scale, about 5 dB below Praat’s for the same recordings (Maryn and Weenink 2015). Converted with the published relation, 4.0 dB is roughly 1.3 dB on the Praat scale, far outside the range of any Praat cutoff here. Rather than convert second-hand values whose task and settings are only partly stated, this reference leaves them as history. The ADSV rows are a separate matter: they are unclassified because no ADSV version is stated where the values are reported (Murton et al. 2020).
Buckley et al. (2023) measured 150 speakers without voice disorders, aged 18–91 years, and proposed normative lower limits at 2 SD below the group mean. Praat CPPS used the Watts et al. settings (version 6.0.50); ADSV used default settings except a CPP threshold of 1 dB and vocalic event detection.
Table 11.4: Normative lower limits for typical speakers (Buckley et al. 2023). The ADSV rows are shown for comparison with the Praat rows; the ADSV version is not stated, so they are not used as reference limits.
Task
Pipeline
Males
Females
Class
Sustained /a/, middle 1 s
Praat 6.0.50 CPPS, Watts et al. settings
11.72 dB
11.05 dB
pipeline-compatible
Sustained /i/, middle 1 s
Praat 6.0.50 CPPS, Watts et al. settings
12.01 dB
10.37 dB
pipeline-compatible
Rainbow Passage, sentences 2–3
Praat 6.0.50 CPPS, Watts et al. settings
6.40 dB
6.49 dB
pipeline-compatible
Sustained /a/, middle 1 s
ADSV CPP; version not stated
8.86 dB
8.09 dB
unclassified (no software version)
Sustained /i/, middle 1 s
ADSV CPP; version not stated
6.68 dB
4.65 dB
unclassified (no software version)
Rainbow Passage, sentences 2–3
ADSV CPP; version not stated
5.40 dB
5.04 dB
unclassified (no software version)
In that sample, 56% of females and 65.3% of males fell below the 9.33-dB Praat cutoff for the Rainbow Passage, and all fell below the 19.10-dB Praat cutoff (Buckley et al. 2023).
Thresholds depend on software, settings and task. Different algorithms produce CPP values in different ranges, and thresholds are lower for continuous speech than for sustained vowels (Murton et al. 2020). On the same samples, ADSV and Praat values correlate highly (r = 0.88), but their absolute values cannot be compared directly (Sauder et al. 2017).
11.5 Confounds and cautions
Software non-interchangeability. On the same MEEI recordings, the sustained-vowel cutoff was 11.46 dB for ADSV and 14.45 dB for Praat. The algorithms can also diverge qualitatively: one speaker measured 11.7 dB in Praat CPPS but 3.5 dB in ADSV CPP, with phonation showing irregular, widely spaced pulses perceived as strain and vocal fry (Murton et al. 2020).
Task effects. CPP thresholds are consistently lower for continuous speech than for sustained vowels. CPP varies widely between different sentences; one possible explanation is their differing amounts of voicing. Comparisons within or between speakers must therefore use the same speech material. The results suggest that including unvoiced frames in the average can artificially lower the CPP of consonant-heavy material (Murton et al. 2020).
Aphonia and voicing detection. Where aphonic segments are included, a low average CPP meaningfully reflects the aphonic quality — but very accurate voicing detection can paradoxically produce a higher-than-expected CPP in intermittent aphonia, because only the periodic voiced fragments enter the average (Murton et al. 2020).
No established upper bound.Murton et al. (2020) note that it is conceivable that some voice disorders lead to abnormally high CPP, which a single threshold would not take into account. They cite Awan and Awan (2020), who indicated that rough voices with a strong subharmonic component may exhibit high CPP values.
Vowel, loudness, sex, and age. Awan et al. (2012), as cited by Murton et al. (2020), found that low vowels such as /a/ tended to have higher CPP than high vowels such as /i/, and that CPP increases significantly with loudness. Murton et al. attribute the loudness effect to increased glottal closure and reduced perturbation, not to a change in underlying dysphonia. Male speakers tended to have higher CPP than female speakers, possibly through loudness. The MEEI controls were 22–59 years old; separate norms for older adults may be needed (Murton et al. 2020).
A higher CPP is not always a better voice. In 50 vocally healthy adults simulating three phonation types, with Praat 6.2.11 CPPS and the settings of Murton et al. (2020), mean CPP was higher in pressed than in typical phonation: by 0.49 dB on an all-voiced sentence and by 1.01 to 1.57 dB on sustained vowels (Toles and Murton 2025). Breathy phonation lowered it, by 2.76 dB on the sentence and 3.13 to 3.93 dB on vowels. The rise with pressing held for women on every vowel. Men showed no difference between pressed and typical phonation on any vowel, only on the sentence (Toles and Murton 2025). With high-speed videoendoscopy, CPP on /i:/ rose with faster and more abrupt glottal closure, correlating −.62 with the closing quotient and .62 with the normalized maximum area declination rate (Toles et al. 2026). The consequence for practice, as both papers put it: a patient with a hyperfunctional voice may sit above a published cutoff and be classified as typical, and a fall in CPP after therapy can then be an improvement (Toles and Murton 2025). Check whether the direction of a change in CPP matches the therapeutic target (Toles et al. 2026). The two studies come from one laboratory and very probably share most of their speakers, so they are not independent confirmations; this is this reference’s inference, and neither paper states it.
A group shift is not an individual test. The pressed-phonation rise is a difference in group means. In the same study’s logistic models, at its own significance level of 0.0125, CPP did not separate pressed from typical phonation on any task (P = 0.464 on the sentence, 0.019 on /ɑ/, 0.060 on /i/ and 0.013 on /u/), and its AUCs for that contrast were only 0.61 to 0.71 (Toles and Murton 2025). For breathy against typical phonation its AUCs were 0.88 to 0.93. The paper’s abstract says CPP differentiated pressed from typical phonation in most tasks; its tables do not support that at its stated significance level, and this chapter follows the tables. These figures are performance metrics from simulated phonation in healthy speakers, not cutoffs. For the spectral measure that did better on this contrast, see Spectral Tilt.
Cutoff vicinity. Published cutoffs are one possible estimate; values near a cutoff deserve further consideration rather than a binary reading (Murton et al. 2020).
Recording conditions. Hardware, microphone placement, environmental noise, and software are known to affect perturbation measures; their impact on CPP and CPPS remains unclear and needs further investigation (Barsties v. Latoszek et al. 2018).
11.6 Validation
The MEEI cutoff study (Murton et al. 2020) and the roughness/breathiness meta-analysis (Barsties v. Latoszek et al. 2018) anchor the evidence summarized above. The meta-analytic sustained-vowel breathiness effect sizes for CPP and CPPS pooled heterogeneous r-values; the authors retained these measures because they had the highest study counts and sample sizes (Barsties v. Latoszek et al. 2018). The tracheoesophageal findings of Maryn et al. (2009) extend the measure’s validity to alaryngeal voice.
PhonaLab is developed by the author of this reference; see Competing interests.
Upload a sustained vowel or a reading passage and compute CPPS on your own recording, with the software and task always reported alongside the value.
Barsties v. Latoszek, Ben, Youri Maryn, Ellen Gerrits, and Marc De Bodt. 2018. “A Meta-Analysis: Acoustic Measurement of Roughness and Breathiness.”Journal of Speech, Language, and Hearing Research 61 (2): 298–323. https://doi.org/10.1044/2017_JSLHR-S-16-0188.
Buckley, Daniel P., Defne Abur, and Cara E. Stepp. 2023. “Normative Values of Cepstral Peak Prominence Measures in Typical Speakers by Sex, Speech Stimuli, and Software Type Across the Life Span.”American Journal of Speech-Language Pathology 32 (4): 1565–77. https://doi.org/10.1044/2023_AJSLP-22-00264.
Lucero, Jorge C. 2026. “Algorithm Verification and Concurrent Validity of a Web-Based Platform for Multiparametric Acoustic Voice Quality Indices.”Journal of Voice, ahead of print. https://doi.org/10.1016/j.jvoice.2026.04.009.
Maryn, Youri, Catherine Dick, Caroline Vandenbruaene, Tom Vauterin, and Tinne Jacobs. 2009. “Spectral, Cepstral, and Multivariate Exploration of Tracheoesophageal Voice Quality in Continuous Speech and Sustained Vowels.”The Laryngoscope 119 (12): 2384–94. https://doi.org/10.1002/lary.20620.
Maryn, Youri, and David Weenink. 2015. “Objective Dysphonia Measures in the Program Praat: Smoothed Cepstral Peak Prominence and Acoustic Voice Quality Index.”Journal of Voice 29 (1): 35–43. https://doi.org/10.1016/j.jvoice.2014.06.015.
Murton, Olivia, Robert Hillman, and Daryush Mehta. 2020. “Cepstral Peak Prominence Values for Clinical Voice Evaluation.”American Journal of Speech-Language Pathology 29 (3): 1596–607. https://doi.org/10.1044/2020_AJSLP-20-00001.
Sauder, Cara, Michelle Bretl, and Tanya Eadie. 2017. “Predicting Voice Disorder Status from Smoothed Measures of Cepstral Peak Prominence Using Praat and Analysis of Dysphonia in Speech and Voice (ADSV).”Journal of Voice 31 (5): 557–66. https://doi.org/10.1016/j.jvoice.2017.01.006.
Toles, Laura E., Avery Moore, Melanie A. Turner Tice, Caroline Crocker Hurt, Rita R. Patel, and Ted Mau. 2026. “Vocal Fold Vibratory Kinematics and Acoustic Correlates in Pressed and Breathy Phonation.”Journal of Speech, Language, and Hearing Research 69: 2417–36. https://doi.org/10.1044/2026_JSLHR-25-00797.
Toles, Laura E., and Olivia Murton. 2025. “Estimating Pressed and Breathy Phonation from Cepstral and Spectral Measures.”Journal of Voice, ahead of print. https://doi.org/10.1016/j.jvoice.2025.02.017.